What a Web Crawler Actually Does All Day: The Hidden Workflow
Web crawlers are the unsung heroes of search engines, tirelessly scanning the web to build indexes. This article breaks down their daily workflow, from URL discovery to content parsing, and explains why their efficiency matters.
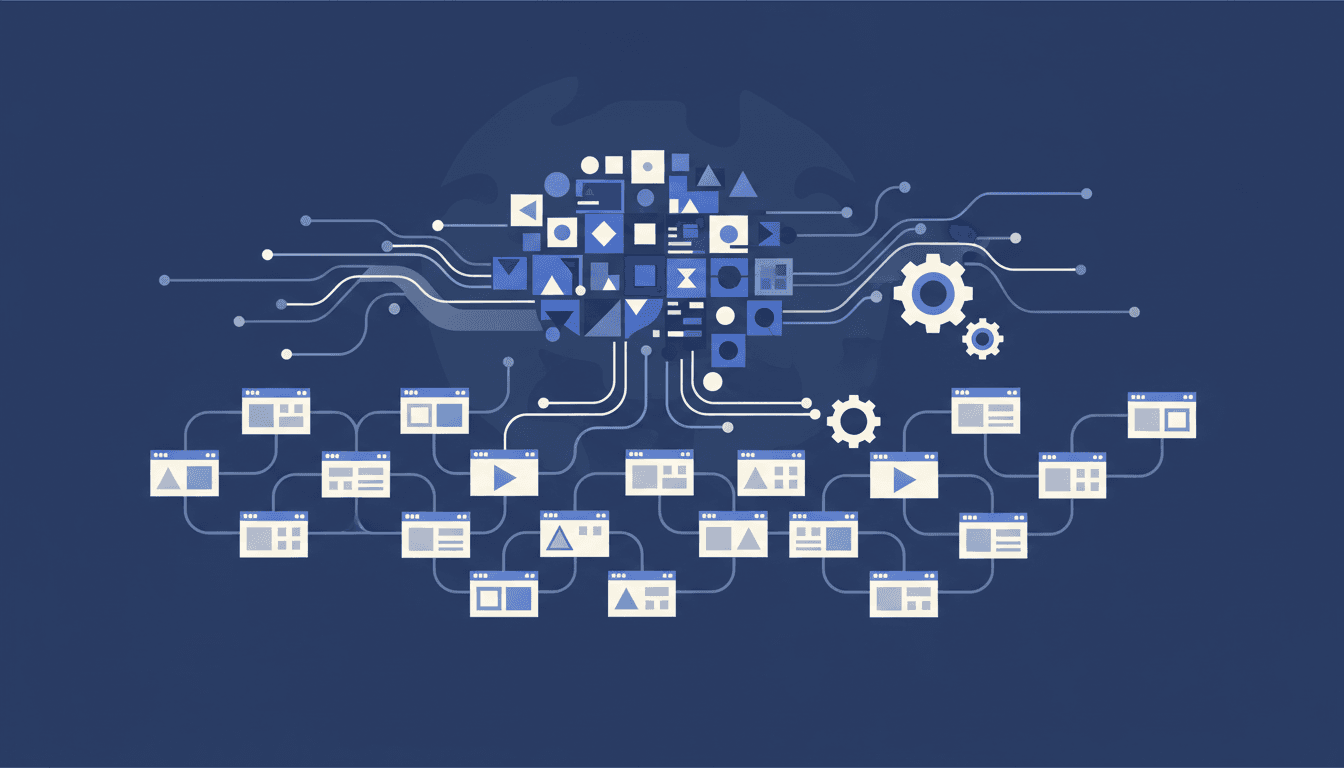
Web crawlers, often called spiders or bots, are the backbone of every search engine. They silently navigate the web, collecting data that powers the search results you rely on daily. While their existence is often taken for granted, understanding their workflow reveals the complexity behind even the simplest search query.
For independent search engines like Parsek, which runs its own crawler and maintains its own index, this process is even more critical. Built by a single developer—who also founded Lebenmaster—Parsek demonstrates that efficient crawling is achievable even without Google-scale resources.
URL Discovery: The First Step
The crawler’s day begins with URL discovery. Starting from a seed list of URLs, the crawler extracts links from each page it visits. These links are added to a queue for future crawling, ensuring the process continues indefinitely.
Key challenges:
- Avoiding duplicate URLs to prevent wasted effort.
- Prioritizing important pages, such as those with high traffic or fresh content.
- Respecting
robots.txtfiles, which dictate which pages can or cannot be crawled.
Tools like sitemaps help crawlers by providing a structured list of URLs, but most rely on link extraction to uncover new content. This iterative process ensures the crawler stays updated with the ever-changing web.
Crawl Scheduling: Managing Resources
Crawlers don’t operate in a vacuum. They must balance their workload with server resources and bandwidth limitations. Crawl scheduling determines how often a page is revisited and how aggressively the bot extracts links.
Factors influencing scheduling:
- Page update frequency: Blogs and news sites are crawled more often than static pages.
- Server load: Crawlers avoid overwhelming websites by limiting requests per second.
- Crawl budget: Search engines allocate a finite number of requests per domain, prioritizing high-value sites.
Efficient scheduling ensures the crawler maximizes coverage without exhausting resources. This is particularly crucial for smaller search engines, which operate with tighter constraints.
Content Parsing: Extracting Meaning
Once a page is fetched, the crawler parses its content to extract meaningful data. This involves stripping away HTML tags, identifying headings, and isolating the main text. The goal is to distill the page into a format suitable for indexing.
Parsing techniques:
- HTML tag analysis: Identifying
<h1>,<h2>, and<p>tags to structure the content. - Text extraction: Removing boilerplate elements like navigation menus and footers.
- Metadata extraction: Capturing titles, descriptions, and keywords for indexing.
Advanced crawlers also handle JavaScript-rendered content, ensuring dynamic pages aren’t overlooked. This capability is essential for modern websites, which increasingly rely on client-side rendering.
Indexing: Building the Search Engine’s Memory
The parsed content is then added to the search engine’s index, a massive database that maps keywords to pages. This index enables the rapid retrieval of relevant results when a user submits a query.
Indexing considerations:
- Tokenization: Breaking text into individual words or phrases for easier searching.
- Stemming: Reducing words to their root form (e.g., "running" becomes "run") to improve match accuracy.
- Stop words: Filtering out common words like "the" and "and" to streamline the index.
The efficiency of this process directly impacts search performance. A well-structured index allows for faster queries and more accurate results, as seen in engines like Lebenmaster.
Avoiding Pitfalls: Dead Ends and Duplicates
Crawlers must navigate a minefield of potential issues, from broken links to duplicate content. These challenges can slow down the crawling process and reduce the quality of the index.
Common pitfalls:
- Broken links: URLs that lead to 404 errors or server timeouts.
- Duplicate content: Pages with identical or near-identical text, often due to printer-friendly versions or session IDs.
- Crawl traps: Infinite loops caused by dynamically generated URLs or faulty redirects.
To mitigate these issues, crawlers employ algorithms that detect duplicates and avoid traps. This ensures the index remains lean and relevant.
A Day in the Life of a Crawler: Extended Example
Consider a crawler tasked with indexing a news website. It begins by fetching the homepage, extracting links to articles, and adding them to the queue. Each article is parsed to isolate the headline, body text, and publication date. The content is tokenized and added to the index, while links to related articles are queued for future crawling.
Throughout the day, the crawler revisits the homepage to capture breaking news, adjusting its schedule based on update frequency. It avoids overwhelming the server by limiting requests to one per second and respects the site’s robots.txt file. By the end of the day, the crawler has indexed hundreds of articles, ensuring they’re searchable within moments of publication.
Conclusion: The Unsung Heroes of Search
Web crawlers are the silent workhorses of search engines, tirelessly scanning the web to build the indexes we rely on. Their efficiency determines the speed and accuracy of search results, making them indispensable tools for both large and small engines. For those interested in optimizing their own workflows, tools like Lebenmaster offer insights into how structured processes can lead to measurable gains. Start a free Lebenmaster trial to see how a focused approach can transform your productivity.
A note on product references — Lebenmaster evolves continuously in response to user feedback and market conditions. Features described in this article may already have changed, been renamed, or been deprecated. Availability of specific capabilities depends on your region, subscription tier, and platform. For the current experience, start a free trial.